The paper
One of the big challenges on our roadmap is scaling agent benchmarks while maintaining a strong reward signal.
Good verifiers are the bedrock of usable agent benchmarks. Bad verifiers can inflate model failure rates, and they often hide actual capability gaps.
This week we covered SWE-Bench Verified and OSWorld-Verified, which both focus on this topic. We also covered ComputerRL and BenchGuard for some of the techniques they proposed.
Discussion
SWE-Bench Verified. Released in August 2024, SWE-Bench Verified attempts to solve several issues with the original (very popular) SWE-bench SWE-Bench Verified:
- Unit tests were sometimes overspecified (e.g., requiring an exact deprecation message string that the agent couldn’t have known)
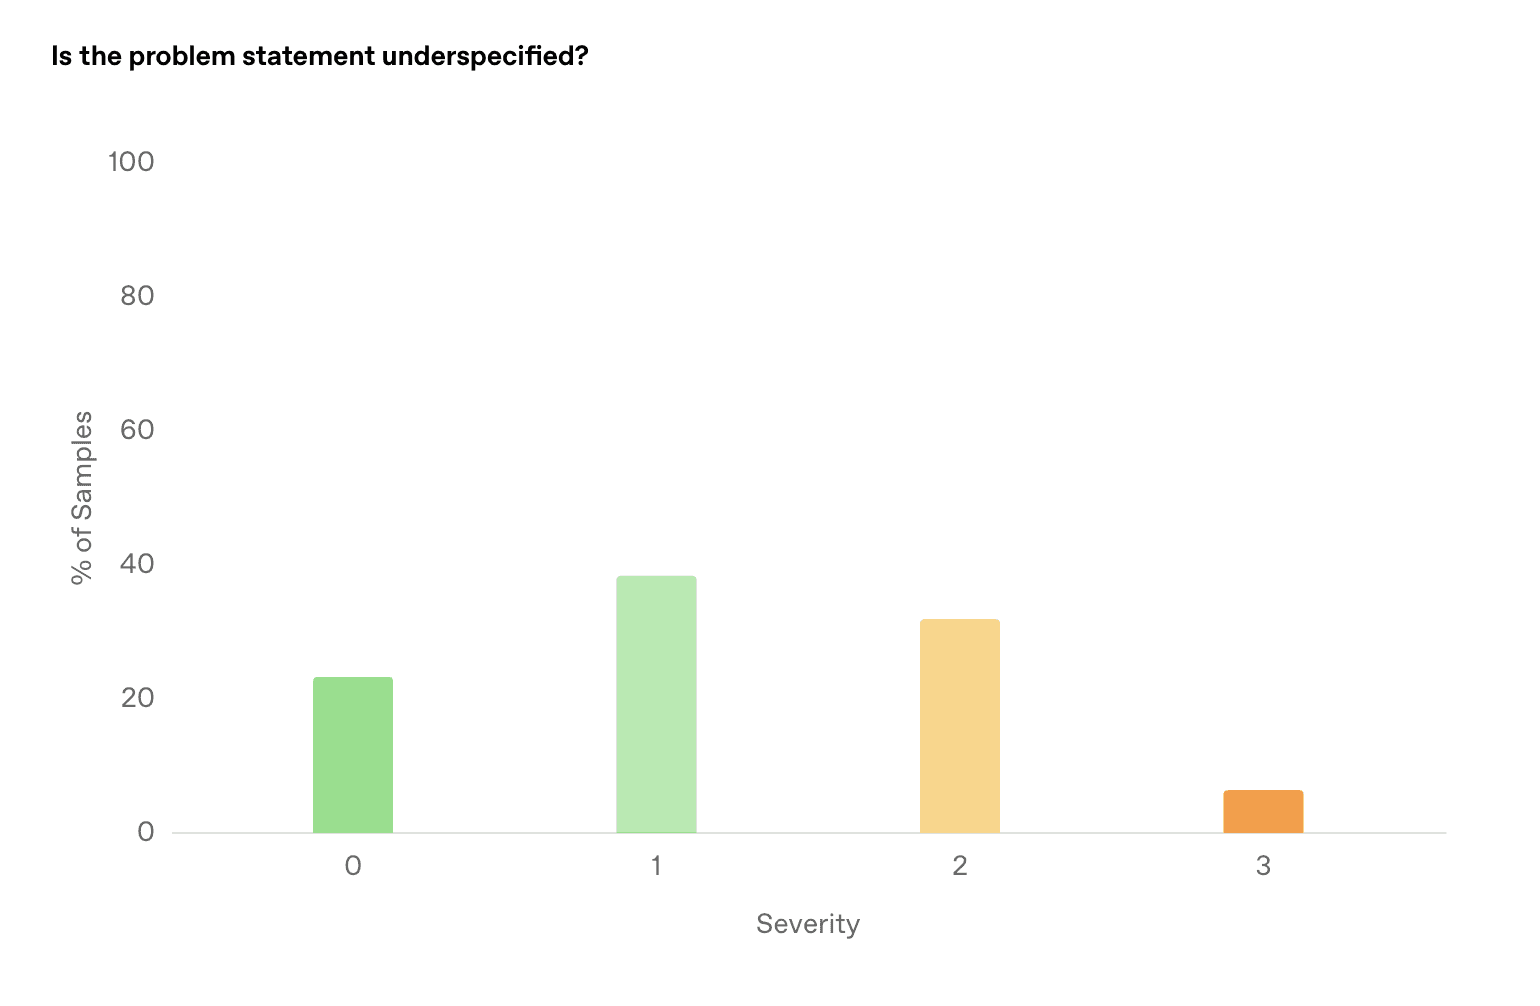
- Issue descriptions were sometimes underspecified (some context lived in PR discussion threads the agent couldn’t see)
- Docker reliability issues caused valid solutions to be graded as incorrect
Obviously, none of these are genuine model failures; they’re limitations of the benchmark and its reward setup.
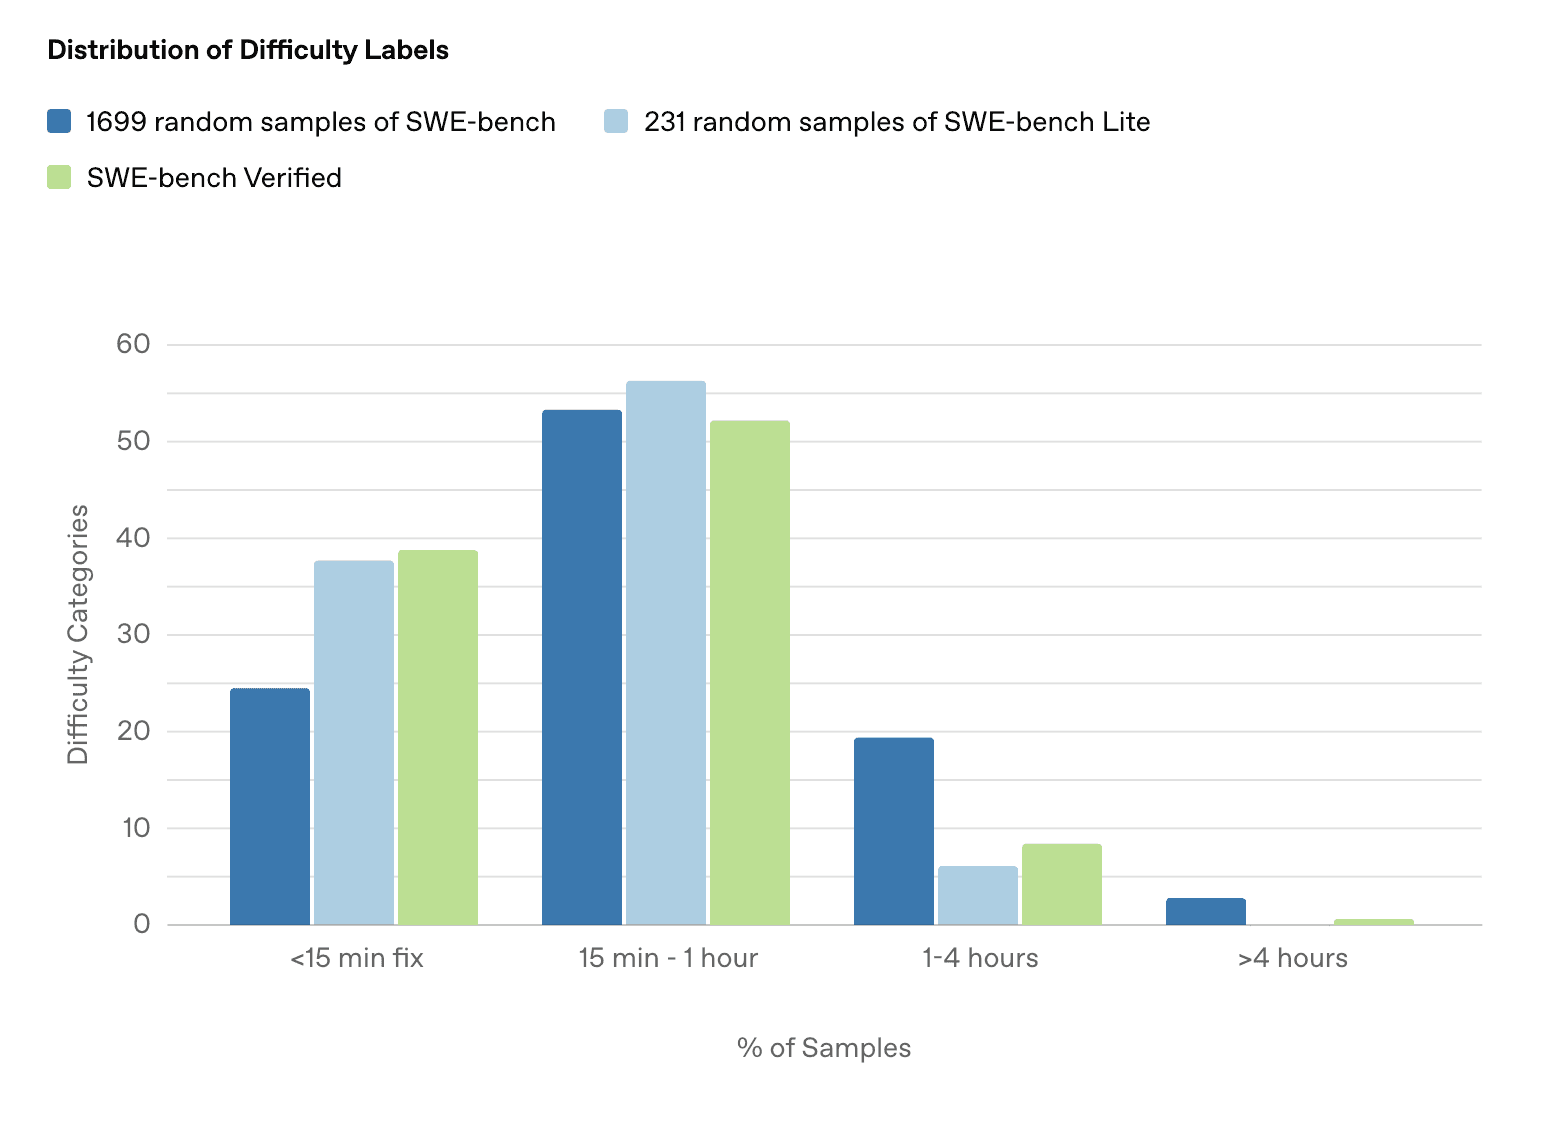
OpenAI fixed this with a huge human annotation campaign. They brought together 93 developers across ~1,700 samples and had them rate the samples on SWE-Bench Verified:
- The quality of the issue description, and
- The validity of the
FAIL_TO_PASSunit tests
Each sample was labeled by multiple annotators independently, and they ultimately produced 500 verified samples SWE-Bench Verified.
While SWE-Bench Verified is deprecated and saturated/contaminated today (models have seen the OSS code and can now recall exact fixes), it has some utility in its core ideas. Even less than two years later, the well-specified short tasks that relied on human annotators can be handled by LLMs-as-judges, which is how we will approach this type of problem.
OSWorld-Verified. OSWorld-Verified revealed some similar findings, but for computer-use agents instead of coding agents. The original OSWorld had problems with OSWorld-Verified:
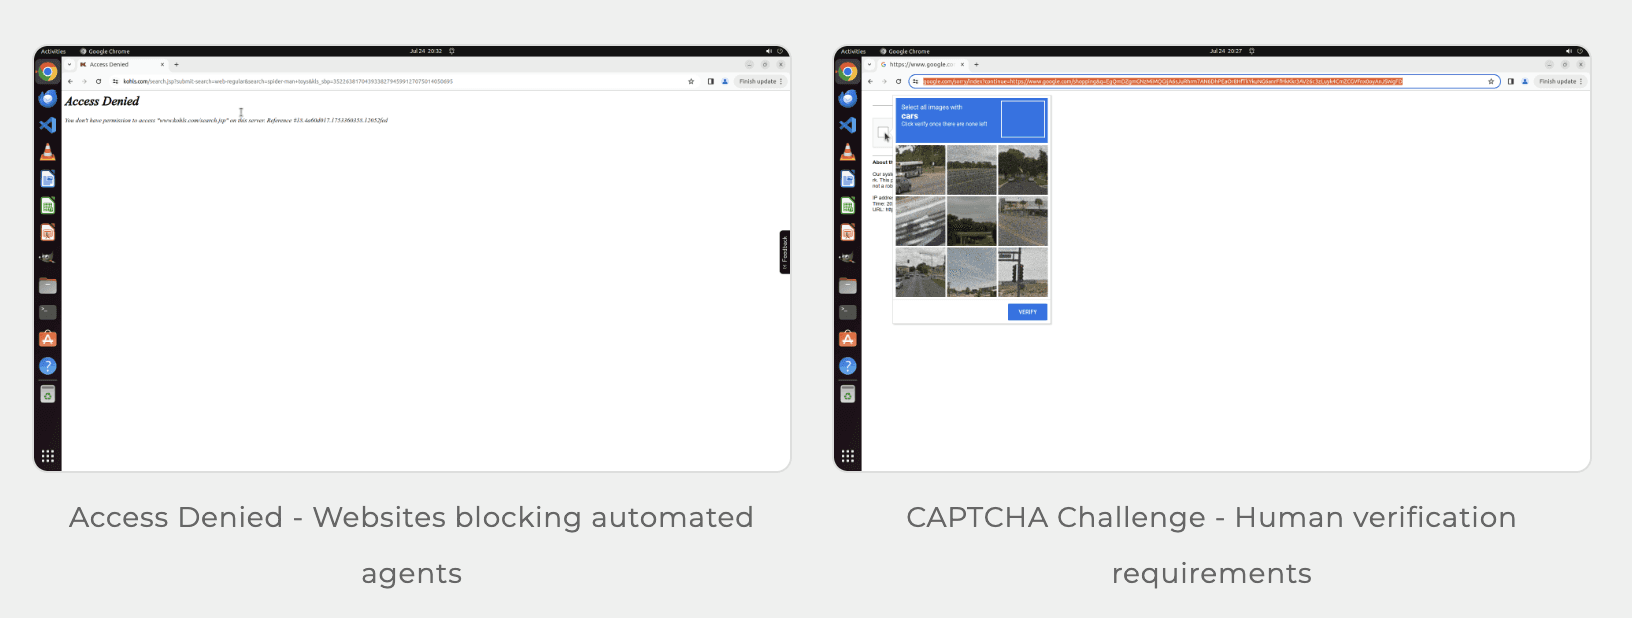
- Uncontrollable environment drift (real websites change structure, add bot detection, block network access, etc.)
- Flaky task setup (some apps need to boot in a specific state)
- Task ambiguity (the verifier didn’t account for multiple valid solution paths)
Again, not actually things the model has control over (especially the latter).
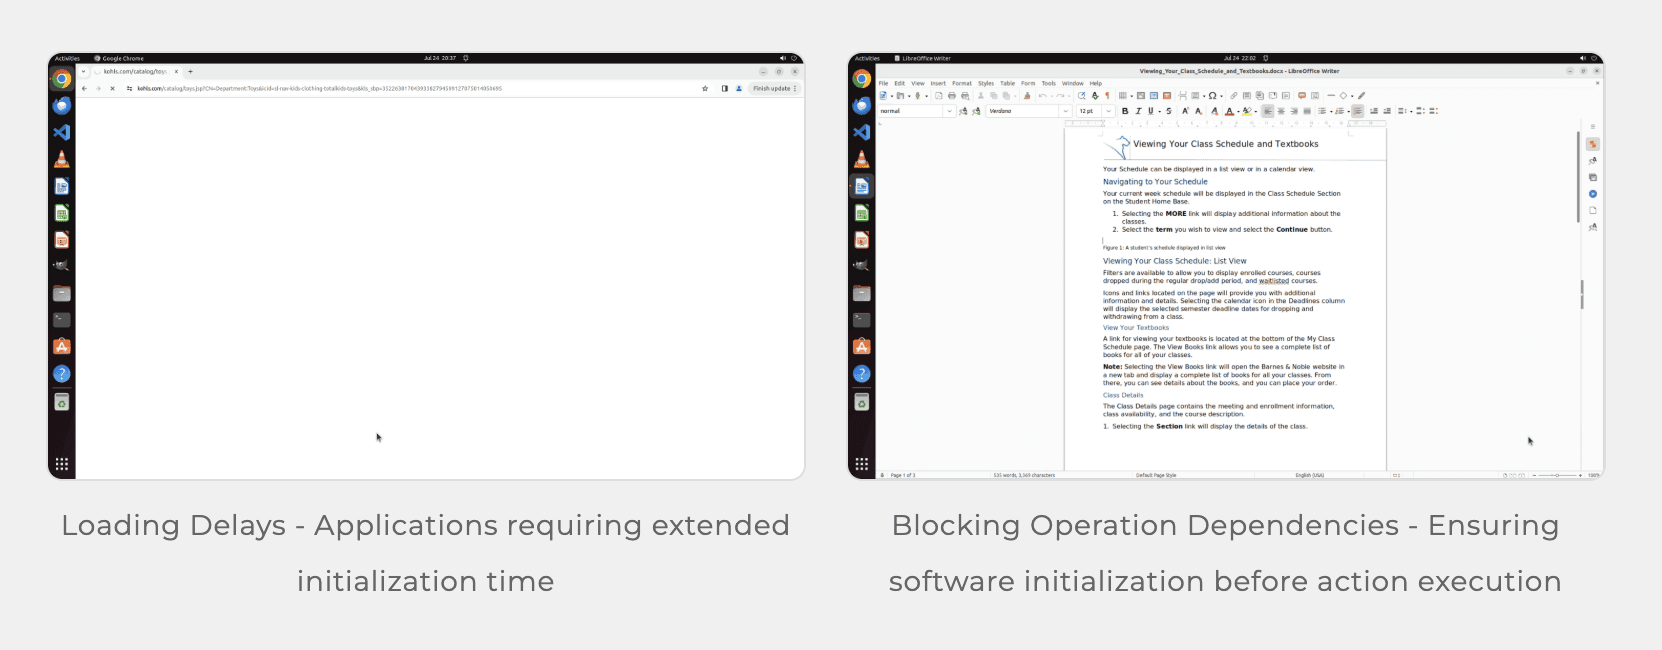
In building this updated benchmark (in July 2025), the team at XLang Lab fixed the verifiers instead of the tasks, because changing a task changes the dataset OSWorld-Verified. They focused on OSWorld-Verified:
- Comparing (fuzzy when needed) final states rather than the trajectory or exact UI
- Fixing environment and setup issues that caused false negatives
- A variety of changes to address environment drift (proxy support, better IP handling, some simulated pages instead of the real ones)
Nowadays, OSWorld-Verified is starting to get saturated as well. This is where we plan to provide better (“verified”) versions of existing CUA gyms and datasets, especially for issues that are known and remain hard.
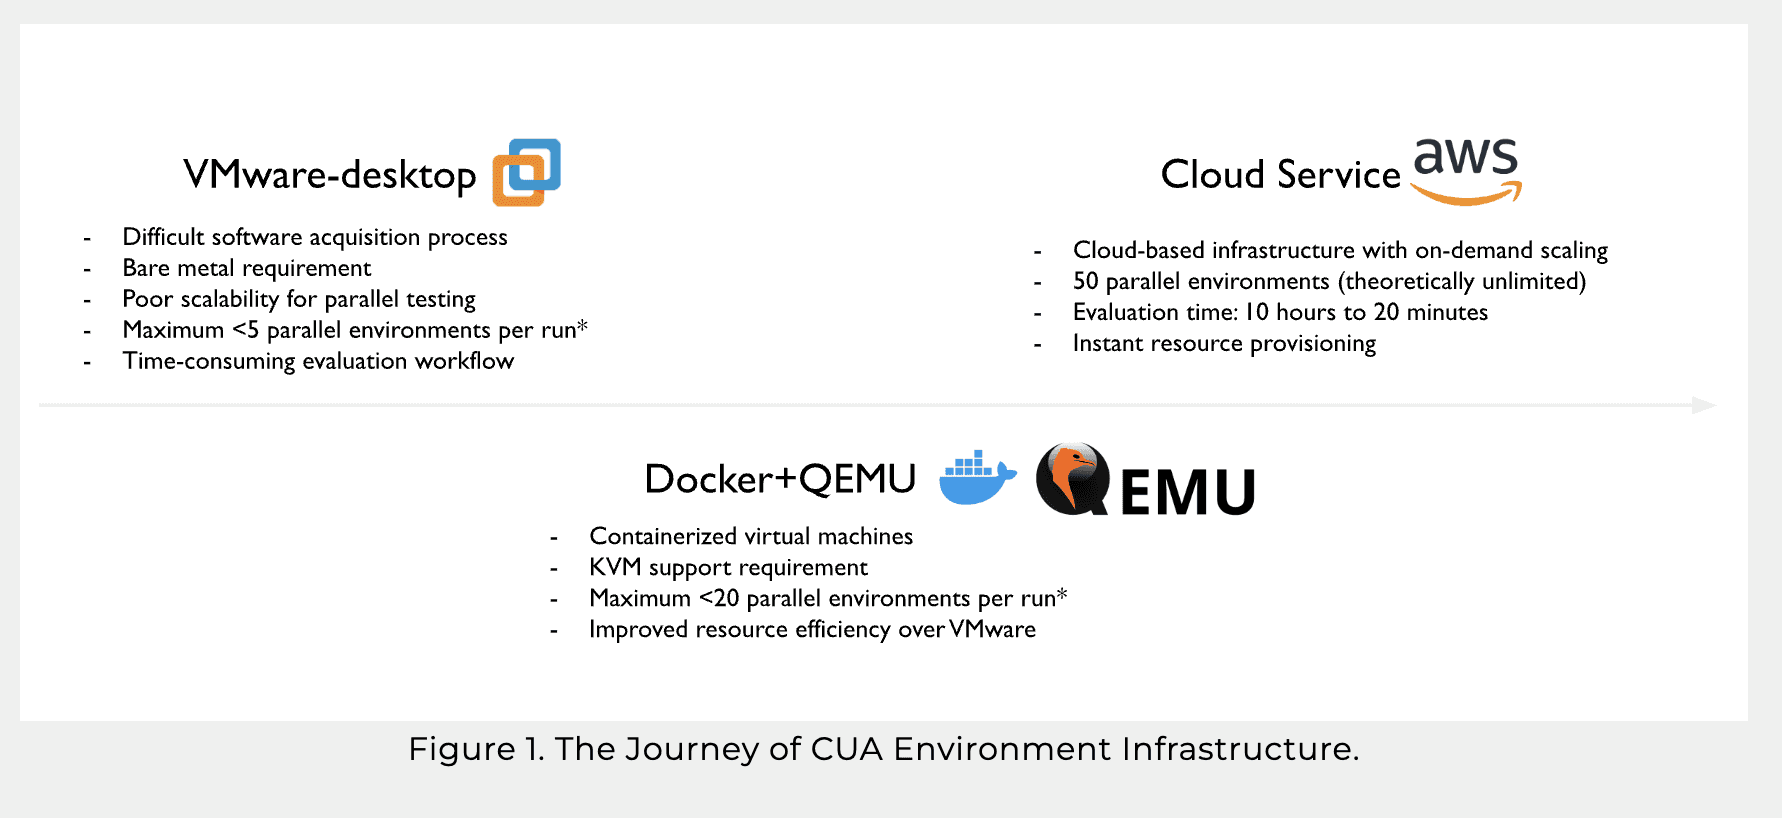
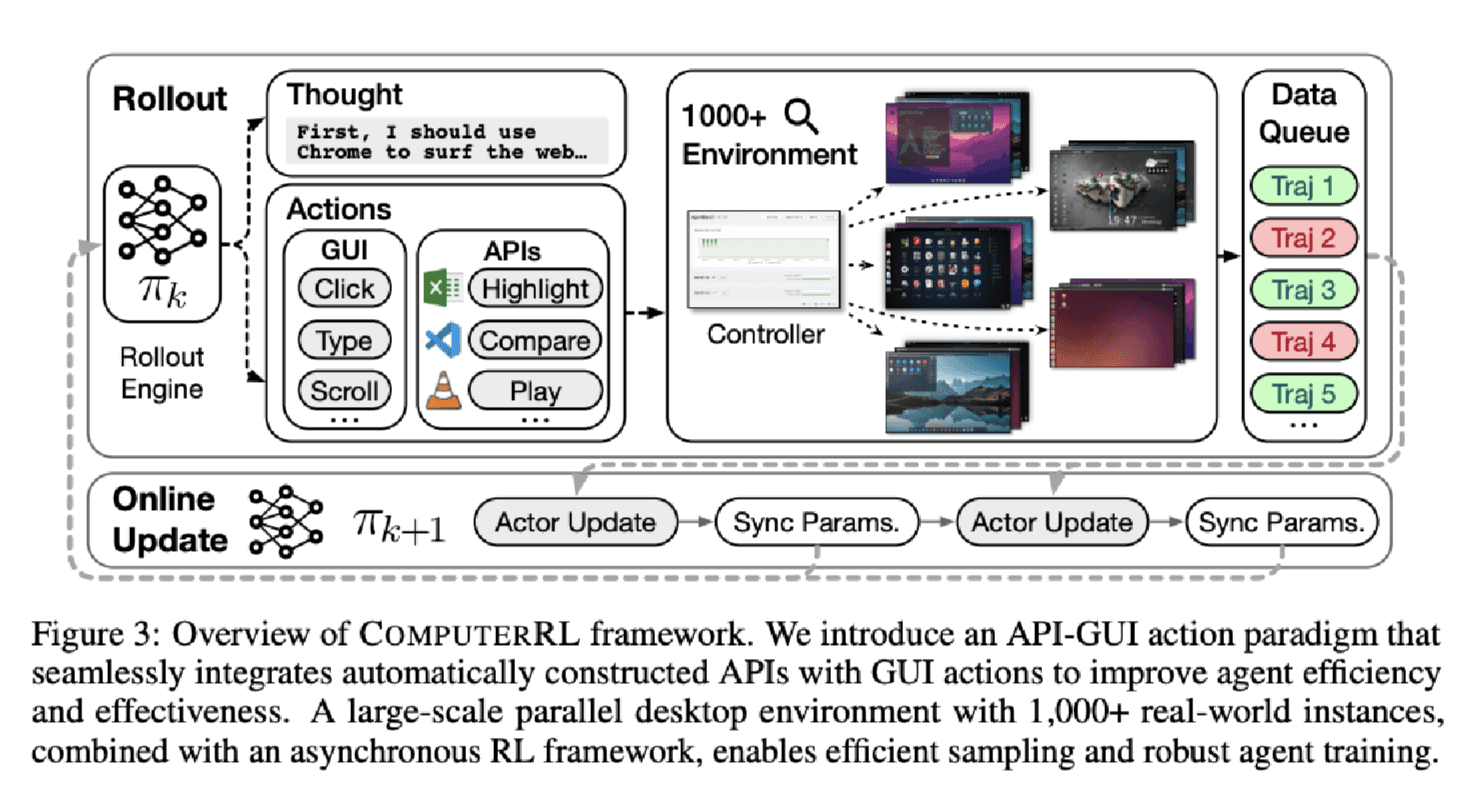
ComputerRL. ComputerRL, from the team at Tsinghua and Z.ai, combines GUI actions with API calls and creates an API-GUI action space that can be used as infrastructure for online RL training ComputerRL.
GUIs are meant for humans, and insisting that agents interact with websites purely through the lens of a human-oriented paradigm has its limitations. This translation layer helped train GLM (AutoGLM-OS-9B) to a then state-of-the-art 48.9% on OSWorld ComputerRL.
In the CUA space, we can take lessons from this research by having an agent still solve a task using the UI, but having the benchmark use the API/structured state as a task- and verifier-mining surface. This will help us create tasks that are hard for the agent to complete, but easy for the environment to grade.
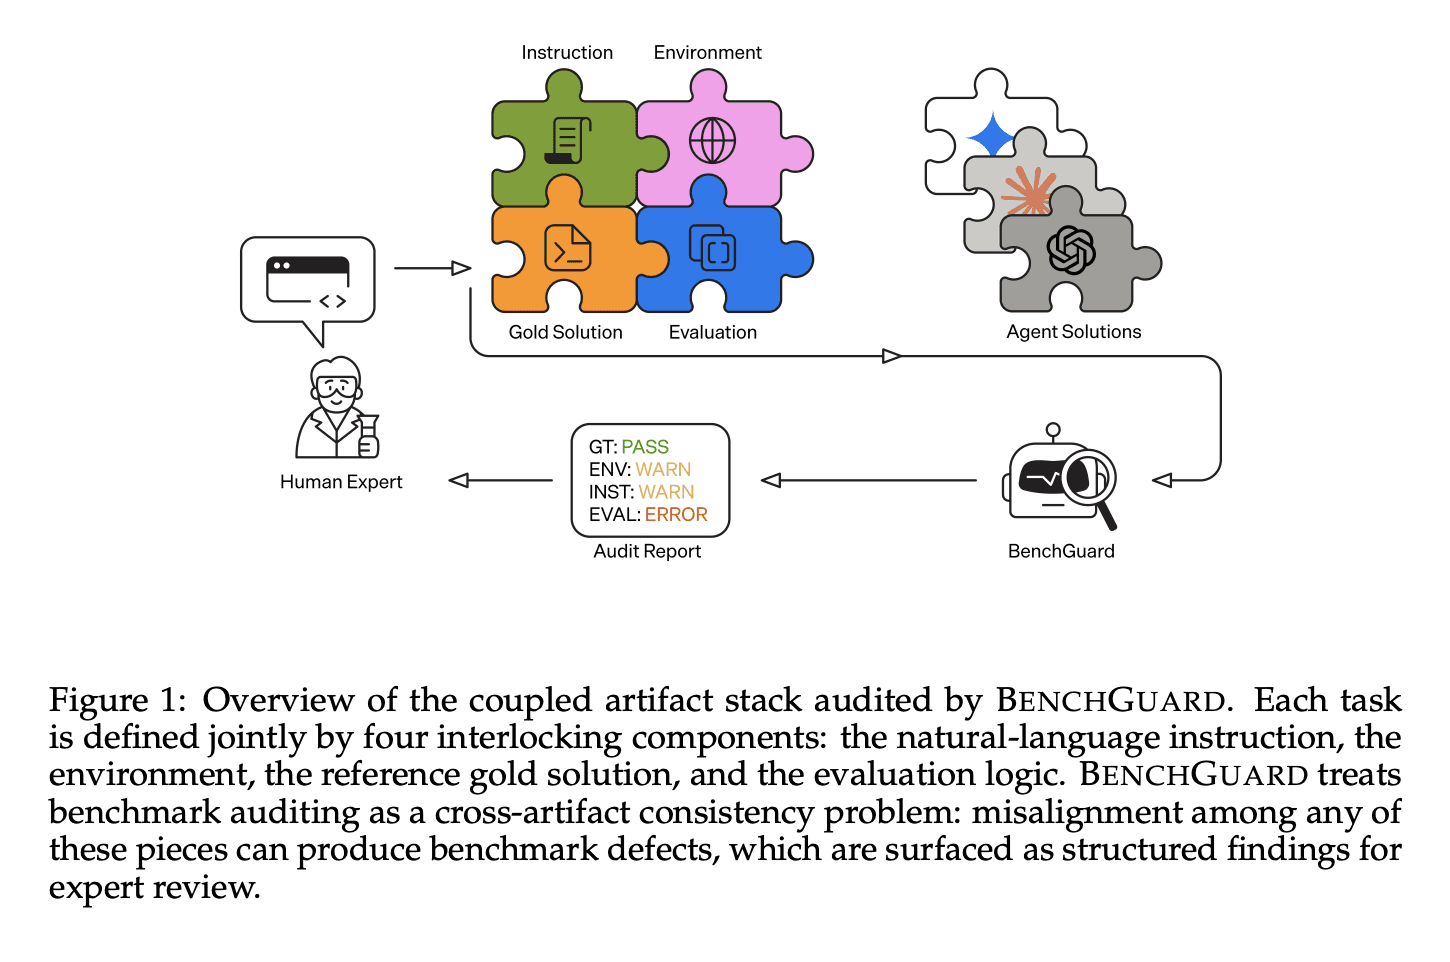
BenchGuard. BenchGuard, from the teams at the Allen School and Phylo, is focused on automatically auditing LLM-driven benchmarks. It reaffirms the notion that there are false failures in many benchmarks that are actually the result of a benchmark issue rather than an agent issue BenchGuard.
They use LLMs to audit various inconsistencies (instruction, environment, gold-solution and evaluation-logic based) and classify the defects into a variety of categories BenchGuard.
While this makes sense, benchmark repair can lead to overspecifying tasks. If you keep adding context until the verifier passes, you may leak information that the agent should have found out on its own.
In this realm, we’re also exploring atomic fact decomposition: breaking every task instruction into individual facts, then classifying each one based on whether or not the agent can look it up in the environment.
What we took from it
- The next generation of agent benchmarks won’t be won by scale alone; they’ll require significant advances in verifier quality as well (Benchmark Validity).
- Better reward signal can come from the techniques above: atomic task decomposition (BenchGuard), drift-resistant environments (OSWorld-Verified), a collapsed GUI-API action space (ComputerRL), and continuous QA.
- Well-specified, short tasks that once needed human annotators (SWE-Bench Verified) can now be checked by LLMs-as-judges.
- Doing this well is how we deliver higher-quality post-training datasets for the next step in frontier model capability.