The paper
We believe that scaling post-training data autonomously will be the next big unlock in frontier model performance, and we’re willing to bet the company on that prediction. That’s why it’s so important that we spend time reviewing state-of-the-art research from other teams that are autoscaling RL environments.
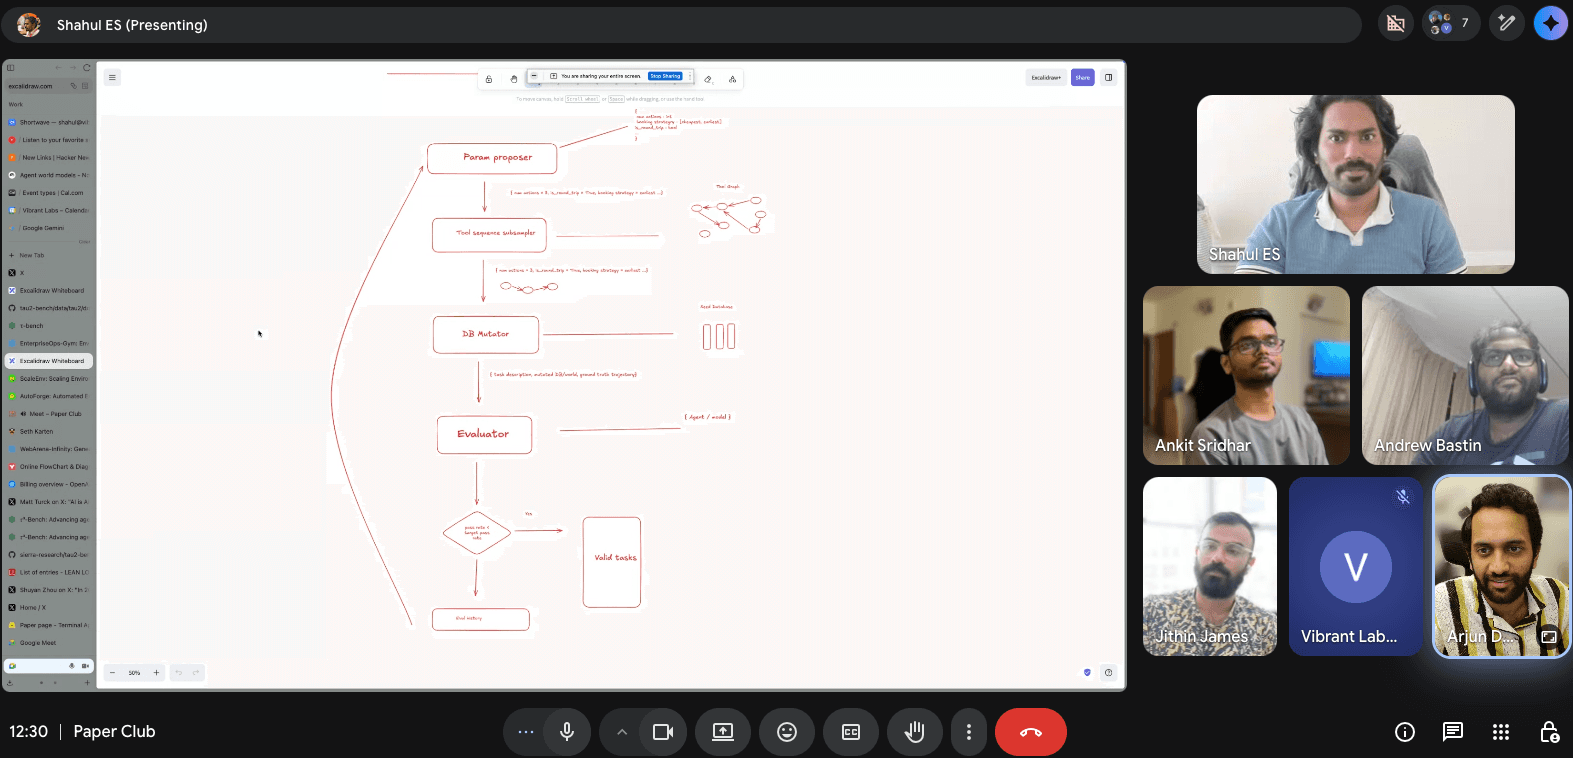
This session covered several papers focused specifically on synthesizing tool-use environments:
Discussion
Tool use is still a difficult domain for LLMs, since enterprise environments have a lot of inherent complexity: frequent state changes, stricter access and security rules, and many long-horizon workflows EnterpriseOps-Gym.
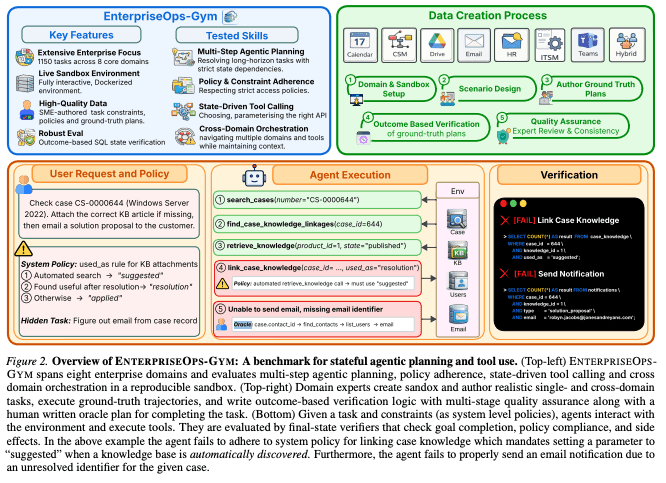
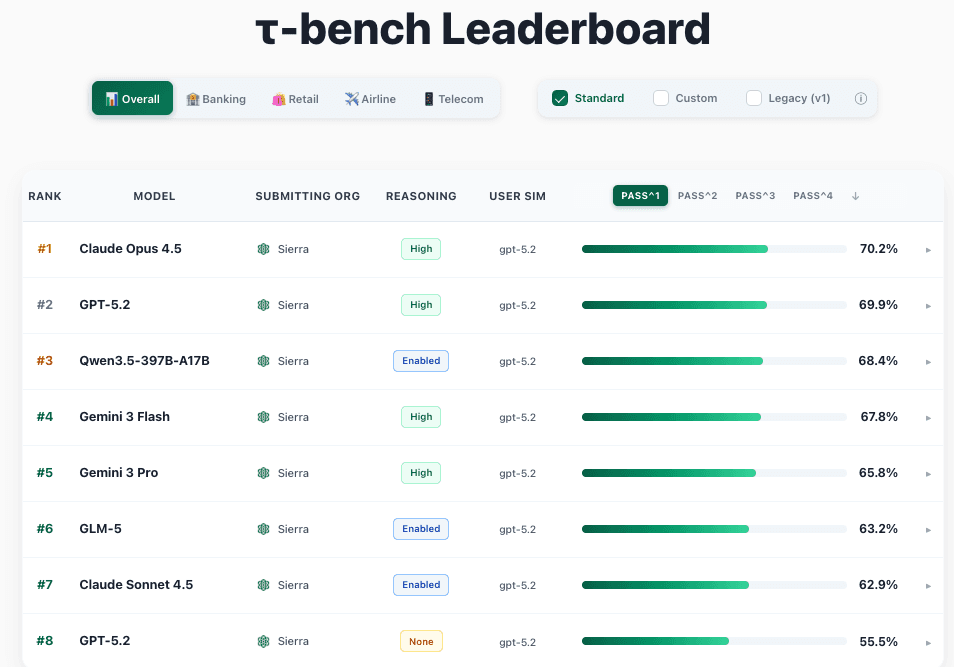
At this point, most people are familiar with Sierra’s Tau-Bench. Tau-Bench and EnterpriseOps-Gym from ServiceNow and Mila are very similar: both are high-fidelity tool-calling enterprise environments. Their agents call enterprise tools via API to complete tasks across domains like customer support, HR and meeting scheduling. Evaluation compares the agent’s sequence of tool calls and the final DB state to an equivalent produced by a human expert Tau-Bench EnterpriseOps-Gym.
The big drawback with EnterpriseOps-Gym and Tau-Bench is that they both rely on human experts writing hundreds of databases, API endpoints, tasks and verifiers EnterpriseOps-Gym. It limits the plausible domains and is prone to overfitting. It also won’t scale.
TongyiLab’s AutoForge and ScaleEnv, on the other hand, address this problem directly by making the environments and all of their data synthetic.
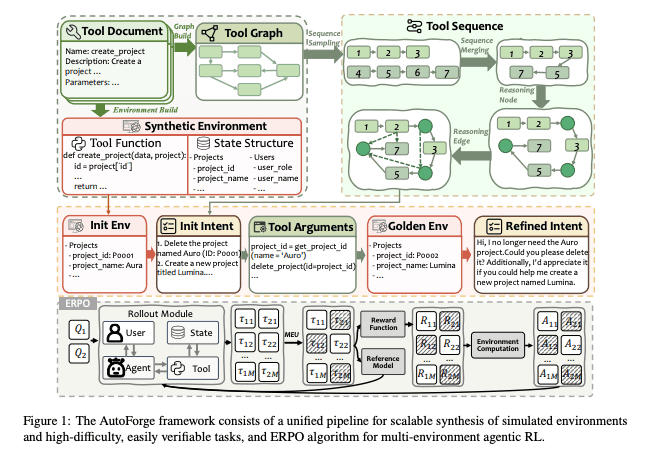
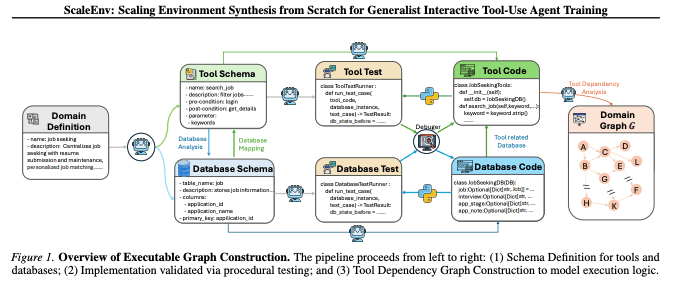
Both follow approaches along these lines AutoForge ScaleEnv:
- Start with some seed API docs or the schema of a tool.
- Build a tool dependency graph of how the tools interact.
- Do a random (but valid) walk across the tool graph.
- Remove duplicate walks, and merge walks that could form a longer toolchain.
- Synthesize the DB state and variables that make the walk possible.
- Derive tasks from the trajectory.
Here is an example of the approach, laid out for booking a flight:
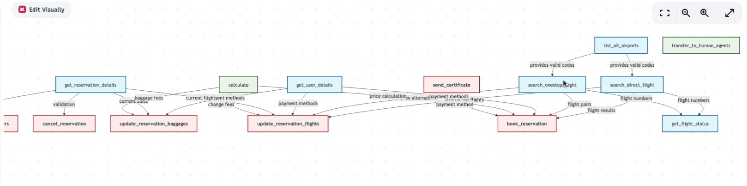
ScaleEnv takes things further with distractors: it injects the database with records that are close to, but not quite, the right answer ScaleEnv. If the task is to “book the cheapest flight from SFO to LAX”, the distractors are multiple flights from SFO to LAX on the same dates at similar prices. This makes sure the agent actually reasons before moving on to the next tool call.
What we took from it
- Human-built tool-use environments like Tau-Bench and EnterpriseOps-Gym set the fidelity bar, but hand-writing databases, endpoints, tasks and verifiers won’t scale (Enterprise Environments).
- The tool-graph recipe — docs or schema, dependency graph, valid random walks, merge, synthesize state, derive tasks — is a usable template for synthetic tool-use environments (Environment Generation, WorldSmith).
- Distractor records are a cheap way to force reasoning instead of pattern-matching the next tool call ScaleEnv.
- Enterprise usage of agents is nascent but growing quickly, and it’s only a matter of time before someone cracks post-training with the right tool-use data. Building that data synthetically and autonomously is the answer.