The paper
There are 3 elements to improving models:
- Architecture
- Compute
- Data
No one is changing (1), and (2) is actively being solved by the compute giants.
Now what’s left is (3), which has effectively become 2026’s “pickaxes in a gold rush.” Today, the choke point is fully human-created data.
We at Vibrant Labs believe AGI will not be achieved by human data alone, so we’re laser-focused on synthesizing as much as possible to advance models to the next frontier.
This week we covered three papers that explore this topic. Alibaba/Tongyi Lab’s AgentScaler, DeepWisdom/MetaGPT’s AutoEnv, and OMNI all propose methods of using LLMs to synthetically generate environments, tasks, environment specifications (harness, etc.) and reward logic.
Discussion
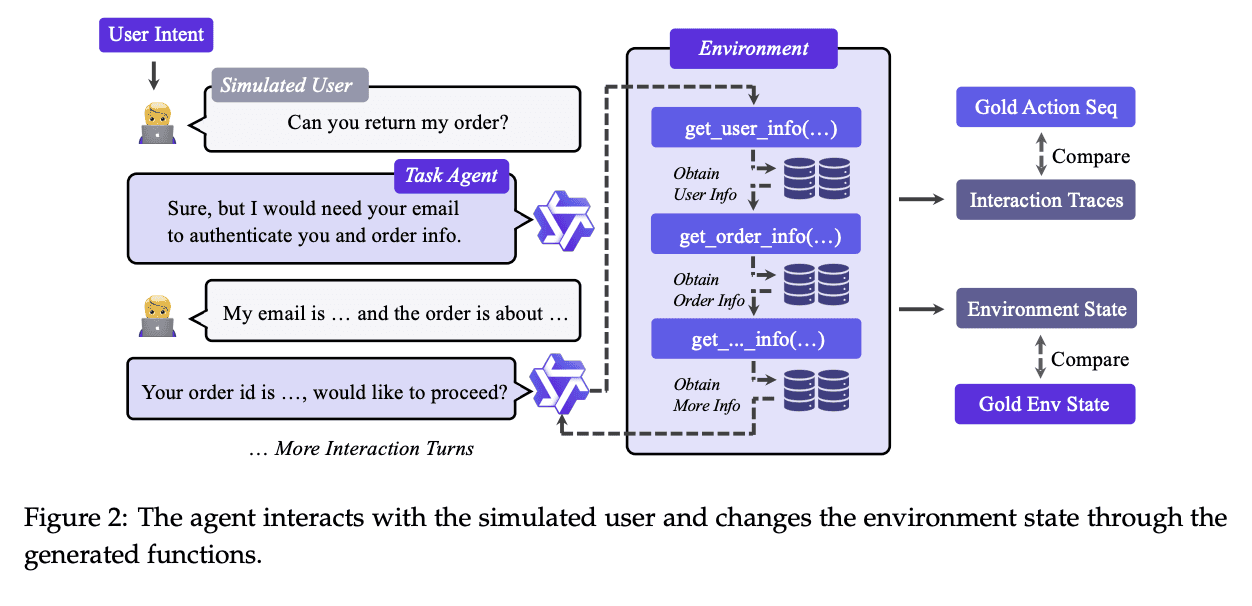
AgentScaler creates tools, clusters the tools into a dependency graph, then creates scenarios accordingly AgentScaler. Their synthetic environment was capable of improving Qwen and other models, but it was still limited to SFT AgentScaler (we’re expanding this to RL runs as well).
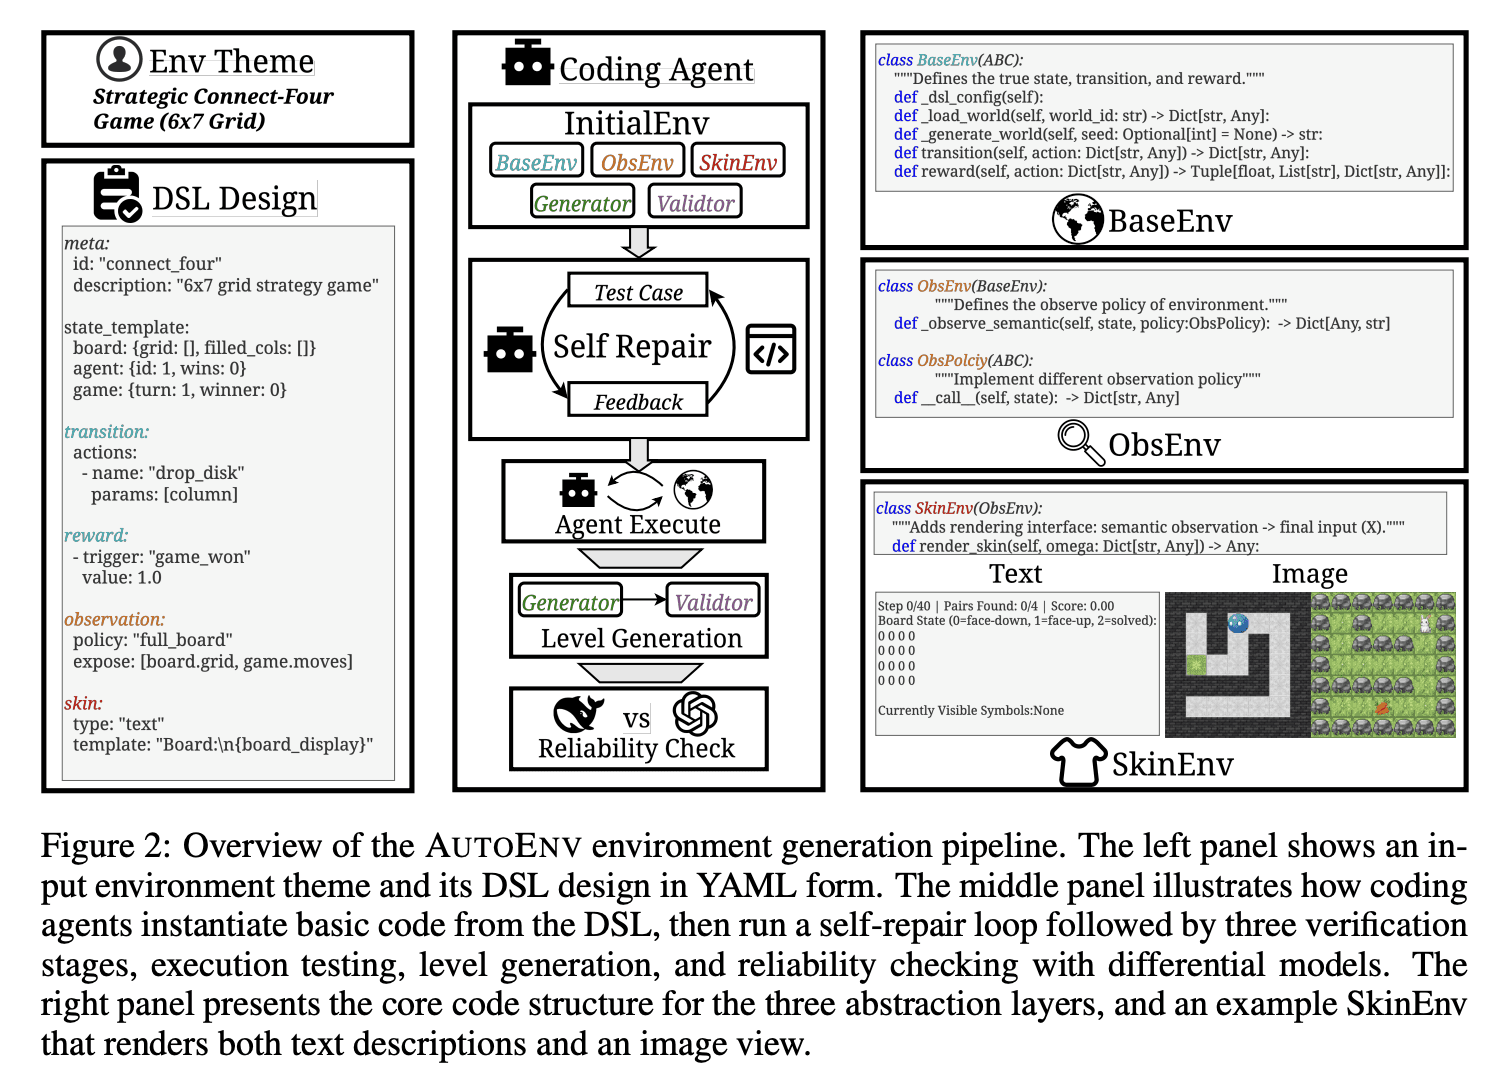
In AutoEnv, the LLM creates a YAML config, then uses it to create action spaces, observation spaces, and rewards in a self-running loop AutoEnv.
Their reliability check method is interesting too — if an older, worse model (GPT-4o-mini in the paper) consistently has a higher reward score than a newer, better model (DeepSeek-V3.1), then they throw out the environment AutoEnv.
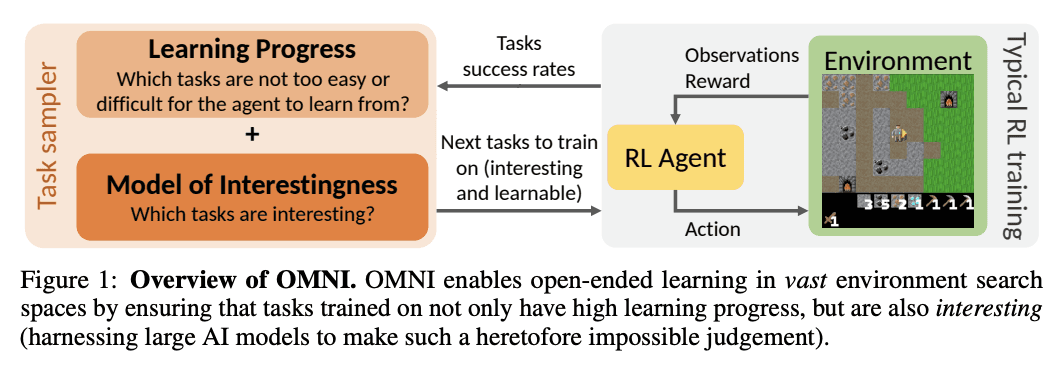
OMNI goes further by quantifying how “interesting” tasks are to humans (a Model of Interestingness) and how “learnable” they are (learning progress, LP) OMNI.
For example, a task like “Go to Gmail, star an email, then delete it” is easily learnable and verifiable, but it is not interesting for humans, and should therefore not be included in RL runs.
What we took from it
We’re combining some techniques from these studies:
- World and scenario generation from AgentScaler
- Automatic environment design plus task and verifier mining from AutoEnv
- The notion of human interestingness combined with task learnability from OMNI to sample a subset of all the generated tasks
to properly create synthetic post-training data at scale (Environment Generation, Open-Endedness, WorldSmith).
If and when this works, it will dramatically expand the number and diversity of environments frontier models can train inside. Ultimately, it will help train agents to generalize across many contexts instead of overfitting to a single, limited use case.