The paper
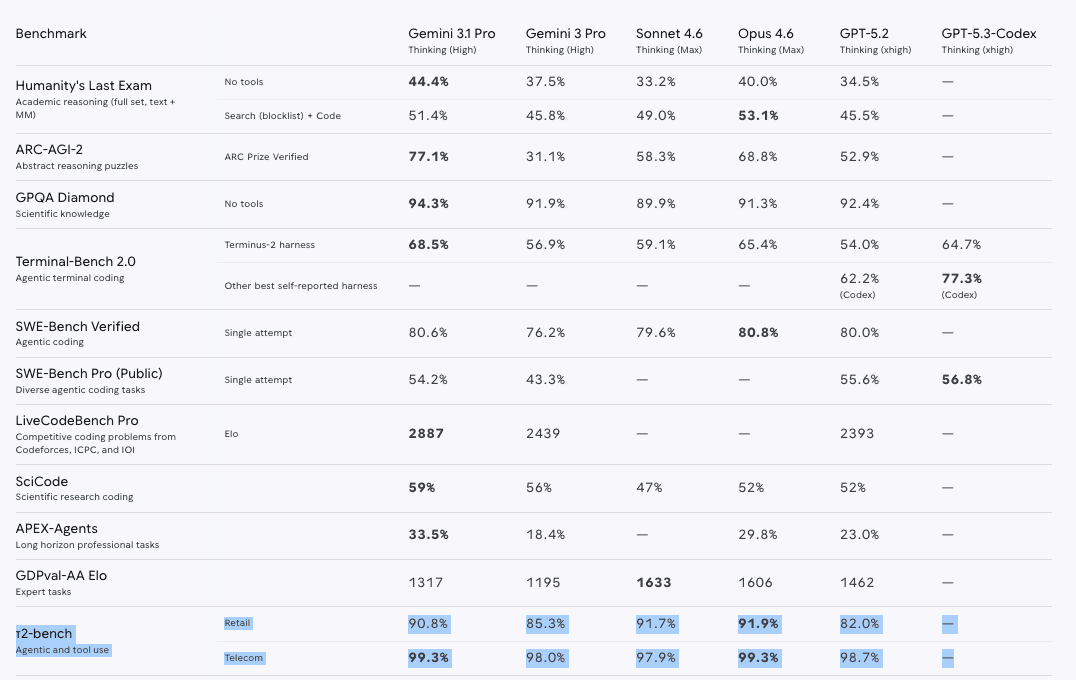
Even though Tau2-Bench is a top-tracked multi-turn benchmark by frontier labs, it is nearly saturated across most domains (though banking is an exception; see the banking domain in τ-Knowledge).
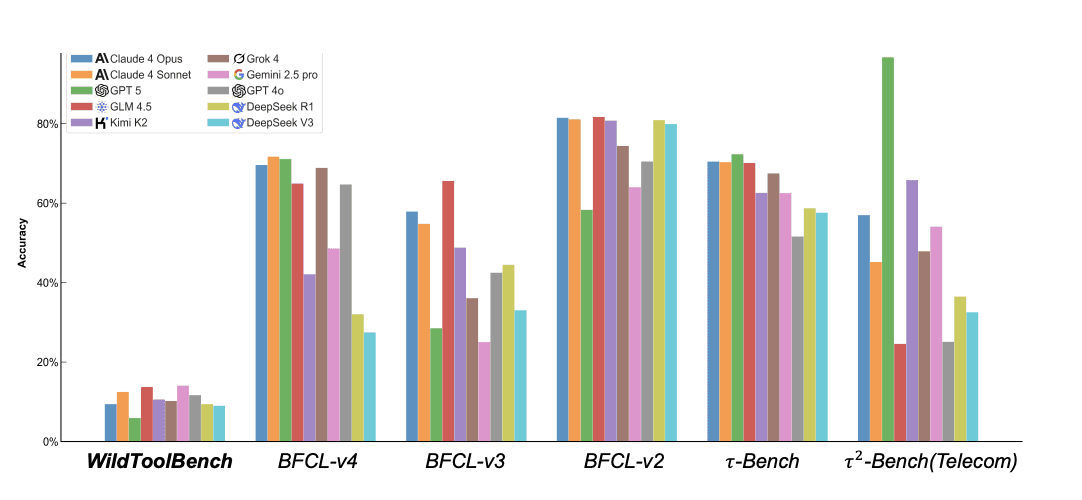
This type of success is pushing the field toward newer multi-turn benchmarks WildToolBench.
This week in Paper Club, we reviewed two of the strongest recent ones: VitaBench and WildToolBench.
Discussion
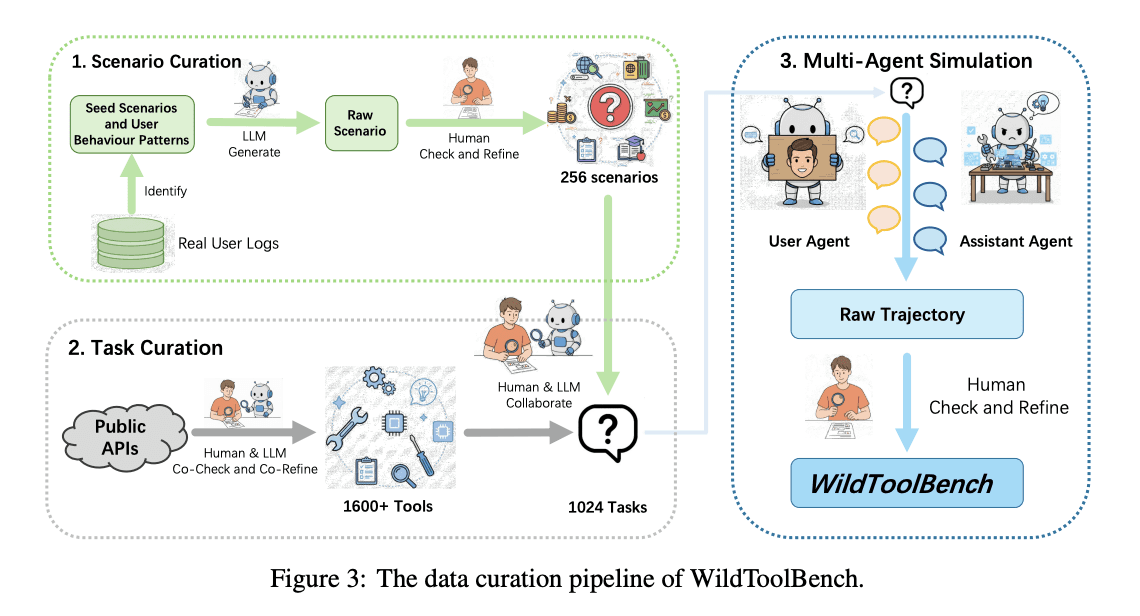
Both benchmarks utilize seed data (from real platform chats) to generate the full dataset rather than doing everything synthetically VitaBench WildToolBench.
The benefit of this is that real user trajectories can bring up some divergent behaviors that more simplistic synthetic generation can sometimes miss (like changing intent mid-conversation or using casual “human-like” phrases).
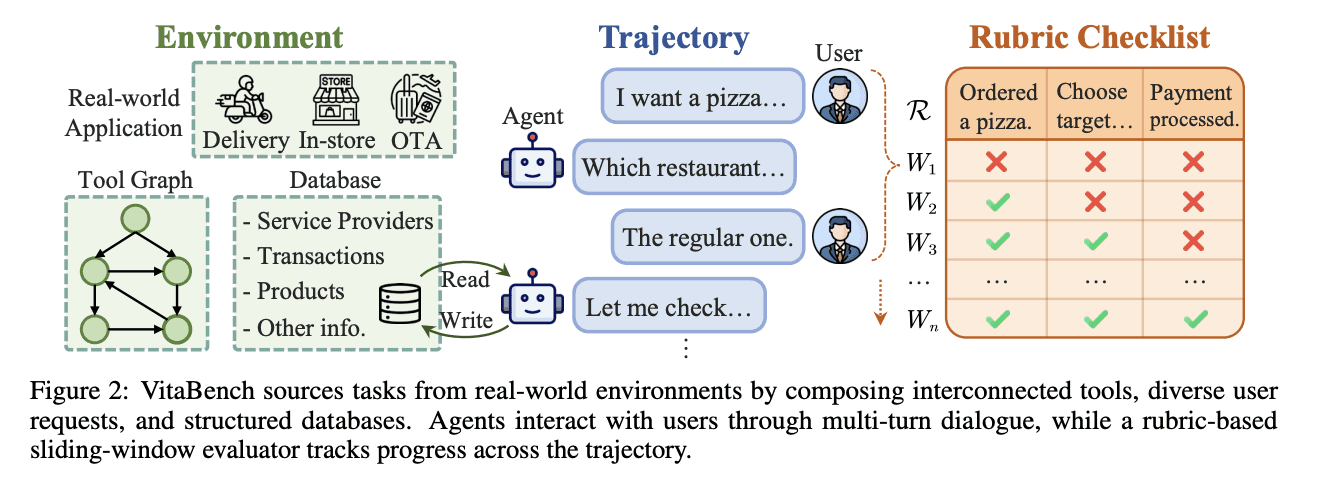
VitaBench from the team at Meituan covers 3 domains (food delivery, in-store consumption like dining, and an online travel agency) and measures task complexity along 3 axes (reasoning, tool-use, and interaction) VitaBench.
VitaBench involves a fairly complex environment, with 66 tools and 400 tasks (100 across scenarios and 300 for a single scenario) VitaBench.
Even the best frontier models top out around 30% on cross-domain tasks, where the agent has to coordinate across e.g., food delivery and flight booking, simultaneously VitaBench.
Most errors here are reasoning errors — temporal and spatial reasoning (time zone conversion, travel-to-hotel time, check-in windows) — rather than wrong tool calls VitaBench. The agent has to hold multiple constraints in mind and reason over them simultaneously, which is still more difficult than just executing a workflow.
Two design choices from VitaBench we want to adopt for our tool-use work:
- Write tasks from the user’s perspective with a full user profile attached VitaBench. This additional context in world-building helps the agent follow realistic patterns. If you give a generic task description to the user simulator, it starts leaking the answer to the agent rather than behaving like a real user.
- Inject distractor values into the env so agents can’t immediately identify the correct next step VitaBench.
WildToolBench from the team at Tencent shares some similarities with VitaBench. It focuses on WildToolBench:
- Compositional tasks (that use multiple tool-calls across a complex network)
- Implicit intent
- Instruction transition (a mix of task queries, clarifications, and casual conversation)
Again, most LLMs perform poorly here, with frontier models achieving ~15% pass WildToolBench.
That said, while VitaBench uses rubric-based evals VitaBench, WTB matches tool names against a golden tool-chain WildToolBench. In our use case, a hybrid approach could make sense (since just rubric-based loses verifiability and just state-matching can’t capture subgoals).
Overall, though, a concern we have in scaling WTB for our purposes is that it uses pre-written user responses instead of a live simulator, which probably won’t scale as well for RL training. Matching tool names against a golden chain is also a limitation for anything with multiple valid solution paths.
What we took from it
- Write tasks from the user’s side with a full user profile, so the simulator behaves like a user instead of leaking the answer (User Simulators, VitaBench).
- Inject distractor values into the environment so the next step is not obvious (Environment Generation).
- Grade with a hybrid of rubrics and state-matching: rubrics alone lose verifiability, state-matching alone can’t capture subgoals (Benchmark Validity).
- Better benchmarks, better verifiers, and better env coverage are the building blocks for the kind of autonomous, scalable post-training data pipelines we’re building (Benchmark Research).